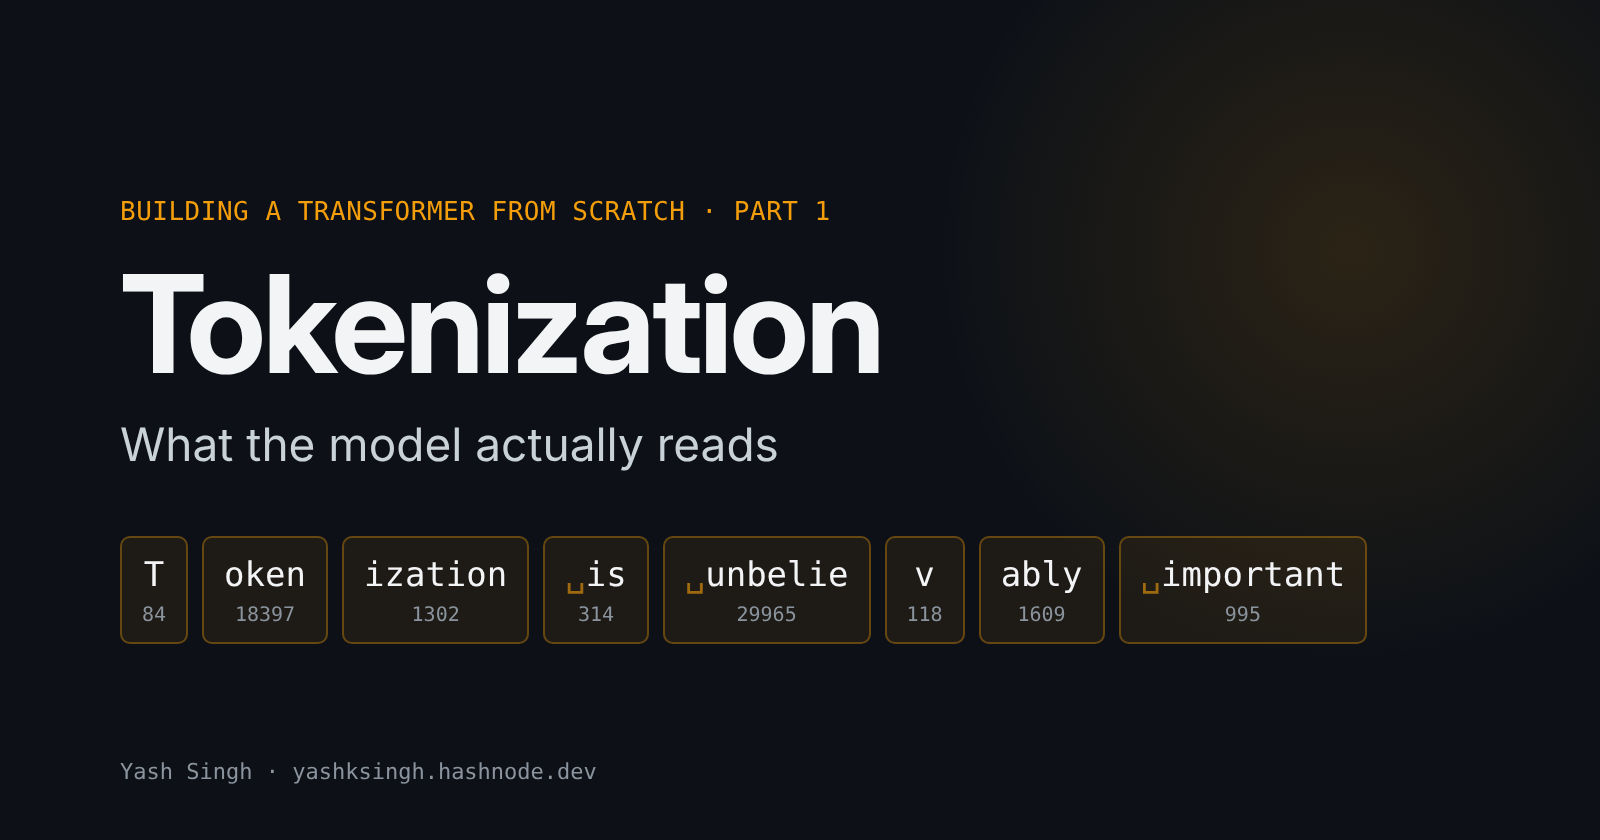
Tokenization Basics: What the Model Actually Reads
Building a Transformer from Scratch, Part 1
Series
I built a GPT-style decoder-only transformer from scratch, tokenizer included, and trained it at two sizes, 110M and 336M parameters, on FineWeb-Edu. This series follows the whole journey one stage per post: tokenization, embeddings, RoPE, attention, LayerNorm, the feed-forward network, training and evaluation, mistakes included.